A diary of where my thinking has been lately.
I've been circling one problem from multiple altitudes for the past few weeks: how does raw semantic material become structured knowledge, and can you engineer that process?
It sounds abstract. It isn't. It's the most practical question I know.
Meaning isn't a thing
Start at the bottom. I've been sitting with this idea that meaning isn't a substance you find or extract. It's relational. It's what happens when a pattern fits into a larger structure in a way that changes what can be understood, predicted, or done.
I keep coming back to protein folding as an analogy. Shape matters. Fit matters. Not every fit works. But the right fit unlocks entirely new possibilities — new binding sites, new functions, new cascading consequences. Meaning works the same way. It's not located in the parts. It emerges from how they lock together under constraint.
This matters because it's not just philosophy. It's the operational foundation for everything I'm trying to build.
The inner refinery
From there I moved one level up: how do transformers actually work? Not the maths — the mechanics of what they're doing to meaning.
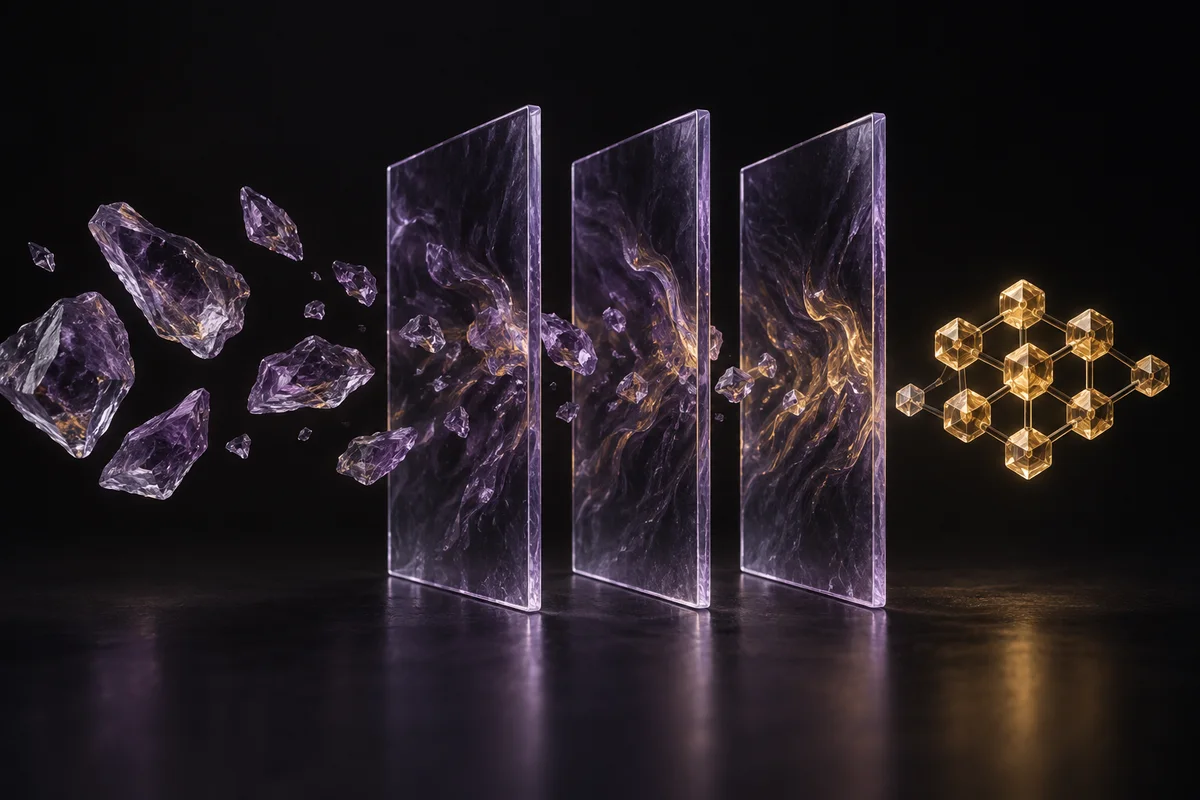
I landed on a metaphor that's become central to how I think about this. A transformer is a layered semantic refinery. Each layer takes the current representational state — this continuous, graded, pre-articulated stuff I'm calling latent semantic material — and reshapes it. Separating, weighting, recombining features under contextual pressure, layer after layer, until it's refined enough to emit as the next piece of language.
That's important. The transformer takes something continuous and field-like and produces something discrete: a word. Meaning may be fundamentally graded underneath — activations smooth, similarity continuous, attractor basins fuzzy — while language and reasoning impose local discretizations on that field.
Meaning begins as latent semantic material and only later crystallises into words.
Where language stops and the real problems start
Here's the thing. Language is where the transformer stops. And language is where the interesting problems start.
Because language smuggles things in. Hidden normative leaps. Definitional slippages. Causal overreach. Unresolved dependencies dressed up as conclusions. The transformer doesn't catch any of that. It can't — by the time those problems exist, it's already done its job. It refined ore into metal. What you do with the metal is someone else's problem.
So you need an outer refinery. Something that takes language-level output and refines it further — not into better language, but into explicit epistemic structure. Into knowledge you can actually reason about.
That's what I've been building.
The Critical Reasoning Faculty
I'm calling the whole system CRF — the Critical Reasoning Faculty. Five layers:
L1 Parse takes raw input and segments it. L2 Clean Well decomposes language into epistemic structure. L3 Evaluate assesses what's been found. L4 Stress-test tries to break it. L5 Synthesize produces the output.
The piece I've been engineering most intensely is Clean Well — the L2 decomposition layer. And the design choice that makes it distinctive is this: Clean Well doesn't judge. It decomposes.
Take a piece of language. Crack it open. Lay out the load-bearing structure. What's the primary claim? What does it depend on? What kind of thing is each dependency — definitional? Empirical? Mechanistic? What's the epistemic status of each piece? Where are the contamination patterns hiding?
And then — critically — stop. The decomposition endpoint is not the validation endpoint. Clean Well maps the structure and preserves the uncertainty. It doesn't decide what's true. That separation is the architectural move that makes the whole thing cohere.
Constrain the ontology, not the local cognition
The design principle I keep returning to is this: constrain the ontology, not the local cognition.
Hard-constrain the object types, the output schema, the terminal categories, the status categories, the contamination classes, the honesty rules, the stopping conditions. These are the walls.
But do not over-constrain the branch order, the traversal path, the intermediate reasoning, the number of branches before pruning. That's the space inside the walls where actual thinking happens.
A prompt, in this framing, is not retrieval. It's guided traversal under induced constraints through a continuous activation landscape. You're shaping a stack of partial attractors with fuzzy edges — constraining the space of possible outputs without scripting the route through it. You're giving the model a constitutional box to work within, not a script to follow.
This maps onto a broader principle that I think is architecturally fundamental: "Intelligence proposes; admissibility disposes." The intelligence layer generates candidates. A separate layer decides which candidates are allowed to count, move forward, or trigger consequences. Being able to think of something is not the same as being allowed to use it. Generation and permission are separate concerns, and they need separate architecture.
Epistemic objects
So what does Clean Well find when it decomposes? It finds what I'm calling epistemic objects — stateful logic components that hold structured epistemic state and can participate in inference, validation, promotion, demotion, and downstream decision-making.
Think of them as coalescence points in semantic flow. Crystallisations. Resting points. Load-bearing condensations where the direction of reasoning changes.
I've arrived at eight master classes: Boundary objects (divide, limit, assign jurisdiction), Reference objects (point to things), Compression objects (reduce complexity by stabilising structure — concepts, principles, schemas, metaphors), Relational objects (connect other objects), Evaluative objects (define what counts and how), Process objects (mark movement through pipelines), Retention objects (preserve stabilised epistemic gains), and Operational objects (translate cognition into action).
These aren't just labels. They're typed, they have lifecycle states, they can be layered in depth from surface to substrate to bedrock, and they're governed by admissibility rules. The taxonomy is the vocabulary the system uses to describe what it finds inside language.
The delta concept
Once you have all this structure, you need persistence. And persistence creates a new possibility: the database becomes an epistemic prior. The system's current structured understanding of the world.
New information doesn't just get appended. It enters as deltas — meaningful mismatches between expected and observed structure. Any time anything veers from the prediction, that's information. That's where value lives.
But I caught the hard problem immediately. Without rules for what counts as a significant mismatch, everything is a delta and nothing is. You need: what counts as expected structure, what mismatches matter, what threshold makes a mismatch significant, what downstream action each delta class triggers. That's still open. It's one of the design problems I haven't cracked yet, and I'm honest about that.
Two refineries, one architecture
So step back and look at the whole picture.
The inner refinery (the transformer) takes latent semantic material and refines it into language. The outer refinery (CRF) takes language and refines it into structured epistemic objects. Two nested processes of successive transformation under constraint. One continuous-to-discrete. The other discrete-to-structured.
And the whole thing is, in a sense, a discretisation machine. It takes something continuous, graded, and field-like — the fuzzy semantic substrate — and imposes structure: this is a claim, this is a premise, this is a terminal, this is empirical, this is definitional, this is weak.
It's compression all the way down. Which is, not coincidentally, the thesis of the book I've been writing.
The book and the system
The Compression Point makes the philosophical case for why this architecture should exist. Compression as the unifying principle across life, mind, meaning, and artificial intelligence. The argument that understanding doesn't come from accumulation — it comes from finding the structure that lets you throw away everything except what matters.
A recent review landed a verdict I think is fair: the book is strong enough to matter, but not yet disciplined enough to fully land. The core thesis — compression defined as source space, representation, fidelity function, and energy cost — gives a usable backbone. The prose has authority. The chapter on language is the standout. But it's trying to be three books at once, and it needs to commit to its strongest identity.
That strongest identity, I think, is the unifying framework. Not the AI warning. Not the meaning-crisis diagnosis. The framework for how compression produces understanding under constraint — in cells, in minds, in machines.
The workshop and the clean room
There's a physical metaphor that captures the state of all this, and it's the state of Open Brain itself — the actual system where I store and connect my thinking.
Open Brain V1 is my workshop. It's messy. Over 1,500 thoughts in there now, connected by nearly 23,000 edges, with projections, analysis runs, an Explorer interface with D3 visualisations, Slack ingestion, document analysis — all grown organically over months of just using it. Dumping ideas in, connecting things when connections appeared, enriching entries when I had time, letting the structure emerge from the work rather than designing it upfront. It's cluttered and alive in the way a workshop is cluttered and alive — tools where I last used them, half-finished things on the bench, but I know where everything is because I put it there.
Open Brain V2 is different. V2 is the CRF layer — eight new database tables designed from first principles to hold epistemic objects, terminals, contaminations, claims with lifecycle states, decomposition links, verification records. It's a clean room being built on top of the workshop. Where V1 grew, V2 is being populated — deliberately, with typed structure, by a system that knows what it's looking for.
The two versions embody the transition I've been thinking about. V1 is how knowledge actually accumulates in practice: messily, associatively, through use. V2 is the hypothesis that you can impose formal epistemic structure on that mess without killing what makes it useful. That the workshop benefits from having a clean room attached to it, rather than being replaced by one.
This is the same tension that runs through the whole project. Continuous versus discrete. Organic versus designed. The fuzzy semantic substrate versus the typed, tracked, admissibility-governed layer that sits on top of it. The question isn't which one is right — it's whether you can build the second without destroying the first.
Where it all connects
CRF is the engineering case for what the book argues philosophically. Clean Well is the first concrete implementation. Open Brain V1 is the workshop where the raw thinking lives. V2 is the clean room being built on top. And the delta concept is the mechanism by which the system learns: not by accumulating everything, but by detecting where new structure deviates meaningfully from existing structure.
One project, seen from different distances.
I don't know exactly where all of this lands yet. Some of it will survive contact with implementation and some won't. The hypothesis stack I've built (six testable claims about whether contract-constrained prompting works, whether decomposition endpoints can be separated from validation endpoints, whether stored priors plus deltas actually reduce repeated reasoning effort) is designed to find out which parts hold up and which parts are wishful thinking.
But the core conviction hasn't shifted: the next step in making AI genuinely useful isn't making models smarter. It's building the refinery around them — the structured process that takes their raw output and transforms it into something you can actually trust, verify, and build on.
The transformer refines representations into language. The CRF refines language into knowledge. The workshop becomes a clean room. And the book tries to explain why that progression is the same story at every scale.
That's where my head has been.
Felix Pope writes about compression, meaning, and the architecture of understanding. His book The Compression Point is forthcoming.